

Hi Friends,
Welcome to the 51st issue of the Polymathic Engineers. This issue is reserved for paid subscribers and will be focused entirely on database replication.
Replicating a database means keeping a copy of the same data in multiple locations that are usually connected by a network. It is a powerful technique that can make your applications faster and more resilient to failures, but it's not as easy as flipping a coin.
There are many options available, and each one has its own tradeoffs. To make the right choice, you need to understand each solution's advantages and guarantees and disadvantages and guarantees that do not provide.
I will give you all the information you need in this article. Here is the outline:
Why replicating a database
Synchronous vs. asynchronous replication
Replication topologies
Single leader replication
Replication Lag
Single leader replication
Failover strategies
Multi Leader replication
Leaderless replication
Why replicating a database
There are three main reasons to replicate a database:
Reduce the latency. Latency is the time that a request is waiting to be handled. Regardless of how fast a database is, read and write operations performance depends on the round trip time between the client that started the request and the server that hosts the database. Replicating helps reduce the latency, keeping the database geographically close to the clients.
Maximize the throughput. At a certain point, a single server can no longer serve all the clients. You can use a more powerful machine and scale vertically or have multiple servers and scale horizontally. In this case, having several databases with the same data helps increase the throughput and serve more clients.
Increase fault tolerance. Saving all the data in a single database server makes the system less resilient to failures. If something bad happens, the clients can't access the data stored on the server anymore. The server may take a while to recover, and the whole system would be unavailable for all that time. So, keeping a copy of the data in other servers allows clients to send their requests anyway, increasing the system's availability.
Synchronous vs. asynchronous replication
The first thing to clarify about database replication is how the data written by the clients is propagated from the server receiving the update to all the other servers.
In this context, the other servers are also called replicas since they are supposed to have all identical copies of the data at a certain point. According to how the data is propagated to the replicas, the replication can be synchronous or asynchronous.
Synchronous replication means that all replicas receive a copy of the data first and then send an acknowledgment to the client.
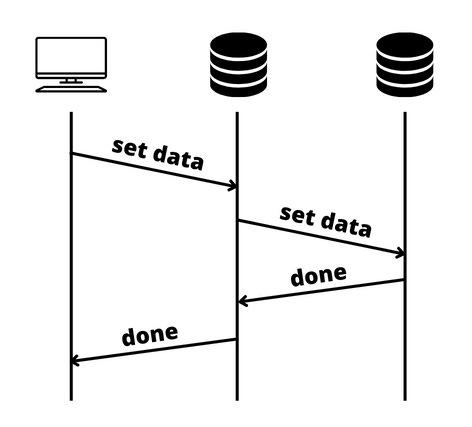
The main advantage of this approach is that the clients can be sure that the data is safe and replicated.
But there is a price to pay for this.
First there is a performance penalty since the processing time of a write request depends on the slowest replica. The waiting time can be significant if a replica is slow or geographically distant.
Second, the availability of the database depends on all the replicas. If a replica is down or can't be reached for some reason, it's impossible to write any data.
Asynchronous replication means that the server receiving the update sends an acknowledge back to the client as soon as it has successfully written the data. Then, it sends the data to the replicas.
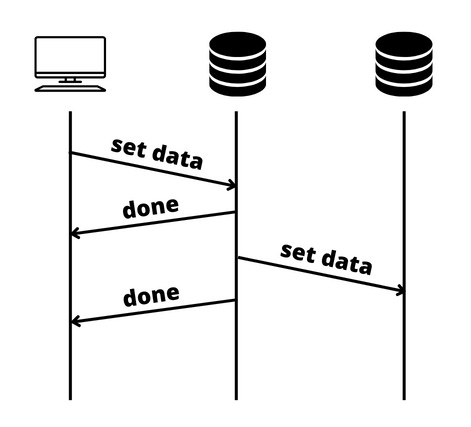
The main advantage of this approach is that it has no performance penalties. But even in this case, there is a price to pay.
First, there is a higher risk of losing the data: if the server that received this write request fails before it can replicate the data, the data is lost even though the client has been acknowledged.
Second, the replicated data is not received simultaneously by the replicas. This means replicas can have a different version of the data when a client reads the data. This problem is known as replication lag, and I'll discuss it later.
Considering the advantages and disadvantages of both approaches, many databases use semi-synchronous replication.
This usually means that one of the followers is synchronous, and the others are asynchronous, guaranteeing an up-to-date copy of the data on at least two servers. For example, PostgreSQL has a synchronous_standby_names parameter to specify which replicas will receive the updates synchronously.
Replication topologies
In general, only some replicas can receive write requests from the clients. There are three main replication topologies to know about:
Single-leader, where a single server can accept write requests, propagating the data to all the replica
Multi-leader, where multiple servers can accept write requests, propagating the data to a subset of replicas and to all the other servers accepting write requests
Leaderless, where every server can accept write requests, propagating the data to all the other servers
Single leader replication
This is the most common replication topology. A single server behaves as a leader, receiving all write requests and propagating the data to all the replicas. The other replicas, called followers, can only receive and handle read requests.
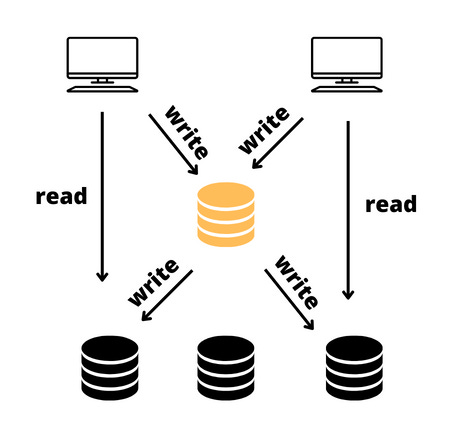
The main benefit of this topology is that it avoids write conflicts since it's impossible for different clients to update the same data simultaneously.
But this benefit comes with some downsides.
First, this topology performs poorly with write-intensive applications since all the update requests go to the leader, which becomes a bottleneck.
Second, the latency for write operations is higher. The leader can only be geographically close to some clients, and the overall round-trip times are higher.
Third, it's necessary to implement a failover strategy in case the leader becomes unavailable.
Failover Strategies
Implementing a failover strategy for the leader is quite tricky and requires solving three main problems:
Being sure that the leader actually failed
Deciding which is the new leader
Making the replicas agree on a new leader
Most databases usually use a timeout to distinguish between a slow-to-answer server and a failed one. Anyway, this mechanism is imperfect, and the timeout must be chosen carefully. We could wrongly assume that a server is unavailable if it's too short. We could waste time waiting for an acknowledgment if it's too long.
Deciding on the new leader is a more straightforward task. Usually, the new leader is a predefined server or the server with the most recent update.
Making the replicas agree on a new leader is more challenging and requires a consensus algorithm like Paxos or Raft.
Replication Lag
The more replicas a single-leader topology uses, the harder it is to use synchronous replication to propagate the data from the leader to the followers.
Indeed, if only one of the many nodes fails when an update is replicated, the whole database becomes unavailable. Asynchronous replication solves this problem but introduces another issue known as replication lag.
The problem is due to the delay between the time the leader applies an update and the time a given replica uses it. If a client reads from this replica during this period, it will receive staled data since the latest updates have not been applied yet.
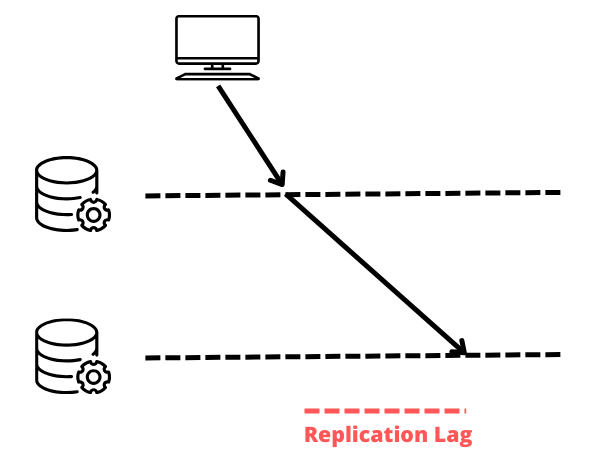
Of course, this may be fine for some applications. For example, for a social network application, it won't be the end of the world if a user cannot see an updated profile picture immediately.
The most common problem is when a client sends a write to the leader and tries to read that data from a replica right away. This is particularly bad because, from the client's point of view, it looks like the write didn't actually work.
The solution to this problem is to direct all the read requests from the client, which made a write to the leader. This is what is called read-your-writes consistency and can be obtained in different ways:
reading data from the leader when it's likely that a client might have changed it
reading data from the leader for a short amount of time after the data has been updated
A second common problem is when a client reads the same data from different replicas multiple times and sees different versions. This is particularly confusing for the client since it is like if the time were moving backwards and forward.
The more straightforward solution to this problem is to make each client always read from the same replica. This is what is called monotonic-reads consistency.
Multi Leader replication
In this topology, more servers behave as leaders, receiving all the write requests and propagating them to the followers. The multi-leader setup addresses some of the issues of the single-leader topology.
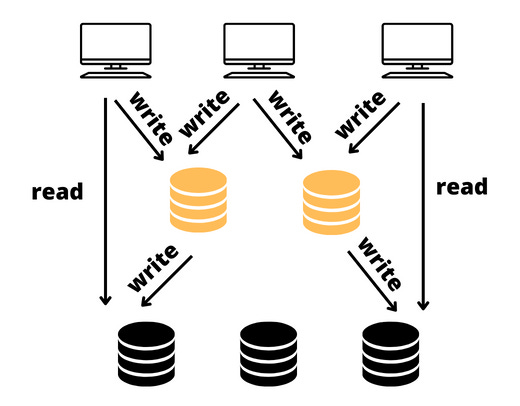
Since multiple databases can accept write requests, they can be geographically distributed and closer to the clients. This both increases the write throughput and reduces the latency.
The drawback is that it's necessary to deal with write conflicts since different servers can receive different versions of the data from different clients. Solving such kind of conflicts is not an easy task, but there are some standard solutions:
Attach a timestamp to each write and let followers apply the write with the highest value. This solution is also called Last Write Wins.
Let the client use some conflict resolution code that can be executed during a write or read request.
Store all the conflicting writes and return them to the clients when they try to read that data. The client then decides which data to keep and writes back to the database.
Use specialized data structures that provide automatic conflict resolution (Conflict-free Replicated Data Type, or CRDT)
Leaderless replication
Each server can accept write requests, and the clients send write and read requests concurrently to multiple servers. As soon as a client gets an acknowledge from a certain number of the servers, a write is considered successful. Since this topology was made popular by DynamoDB, all the databases using this approach are known as Dynamo-style databases.
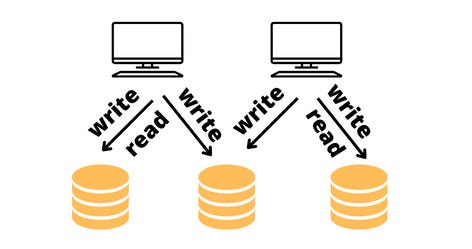
The main benefit of this approach is that failures are tolerated more efficiently without the need for failover strategies. However, having no leader handle synchronization between the servers causes other issues.
First, the corresponding servers will have stale data if some write fails. To deal with this problem, the clients must read data from several replicas concurrently.
The replicas then return their data with some version number, and the clients can use this number to decide which data to keep and which to discard.
Two common techniques can be used to keep servers having staled data synchronized:
read repair: when a client detects that a read data is stale, it sends a write request with the correct data
background process: a background process periodically synchronizes all database instances.
An important point to discuss about leaderless replication is how much servers need to acknowledge a write request to be considered successful.
Suppose we have 5 servers: A, B, C, D, E. If we require a successful write for only 2 of them (e.g., A, B), and we read from 2 (i.e., C, D), we will read staled data. To guarantee that we will read up-to-date data, we must require a successful write in 3 servers and read from 3 servers. In this way, there’s always an overlap between the server that received the write and the one we are reading from.
This idea can be generalized in the following rule. If there are n servers, the number of servers accepting writes (w) and the number of servers from where we read must be such that w + r > n.
Finding the proper balance between n and r depends on the specific usage pattern of the database. Of course, you can also choose smaller values for r w and r. It will be more likely that you read stale values, but you will have lower latency and higher availability.
Conclusion
Replication is a great technique to increase the availability and scalability of a database, reducing the latency. However, replicating a database is a challenging task.
In this issue, we looked at different approaches that can be used to replicate a database. Single-leader, multi-leader, and leaderless replication are all valid approaches, each with pros and cons.
Single-leader replication is popular because it is easy to understand, and you don’t need to deal with conflict resolution. Conversely, multi-leader and leaderless replication can be more resilient to failures or network interruptions at the price of being more complex and providing minor data consistency.
Finally, we also looked at some problems related to database replication, like the replication lag, and discussed how to overcome them.
I hope you enjoyed the article. If you want to give me any feedback or suggestions for the following issues reserved to paid subscribers, please drop me a mail.
I’ll read it very carefully and take it into account. If you liked the issue, please also leave a review and spread the word so more people can join our community.